Column · @getdataopshouse
Why Data Ops Is the Missing Link in Industrial Digital Transformation
Industrial data has a distance problem
Walk onto any factory floor today and you will see sensors, PLCs, edge gateways, and cloud dashboards. The equipment talks, the data flows, and somewhere a team is trying to make sense of it all. But the gap between collecting data and acting on it remains stubbornly wide. That gap is not about hardware. It is about how you operate data once it exists. This is where data ops enters the conversation, and it is a discipline that industrial teams often overlook until they hit a wall.
I have spent years working with manufacturing sites that invested heavily in sensors and connectivity, only to find that their real-time data never quite reaches the people who need it. Engineers end up exporting CSV files from a time-series database, cleaning them in Excel, and then feeding them into a dashboard that updates once a day. By the time a trend becomes visible, the machine has already drifted out of spec. The problem is not the data itself. The problem is the operations around that data.
What data ops means for a factory floor
Data ops, short for data operations, is the set of practices, pipelines, and governance rules that keep data flowing reliably from source to consumption. In an industrial context, it covers everything from how an OPC UA server publishes a temperature reading to how that reading lands in a digital twin and triggers an alert. It is the discipline between the sensor and the decision.
When I talk to plant managers about data ops, I often start with a simple question: how long does it take for a change on the machine to appear in your analytics tool? The answers range from seconds to weeks. The teams that answer "seconds" are the ones who have invested in stream processing, edge computing, and a solid data pipeline. The teams that answer "weeks" are still moving files around manually.
That gap is where data ops becomes a competitive advantage. A well-run data operation makes real-time data a reality, not a promise. It means your digital twin updates as the machine runs, not after a batch job finishes at midnight.
The technology stack behind modern data ops
Building a data ops capability requires more than a single tool. It is a stack that spans the edge and the cloud. Let us walk through the pieces that matter most in industrial settings.
On the edge, you have industrial IoT devices and controllers that speak protocols like OPC UA and MQTT. These are not new, but how you handle their output has changed. Instead of dumping everything into a single database, modern architectures use stream processing to filter, aggregate, and enrich data as it arrives. This reduces the load on central storage and makes alerts possible in milliseconds.
From there, data moves into a time-series database or a data fabric that can handle high write rates and fast queries. Kafka often appears here as the backbone of the data pipeline, decoupling producers from consumers so that a new dashboard or analytics model does not require rewiring the whole plant.
Above that sits the data catalog, a sometimes underappreciated layer that documents what each data stream means, where it came from, and who owns it. Without a catalog, your data ops team spends half their time reverse-engineering signals. With one, they spend their time improving models and governance.
Governance and sovereignty in a connected plant
The more data you move, the more you need data governance. In industrial environments, data sovereignty is not just a legal concern. It is a practical one. When a machine on your floor sends data to a cloud platform hosted in another country, do you still control that data? Can you shut off the flow if the platform changes its terms?
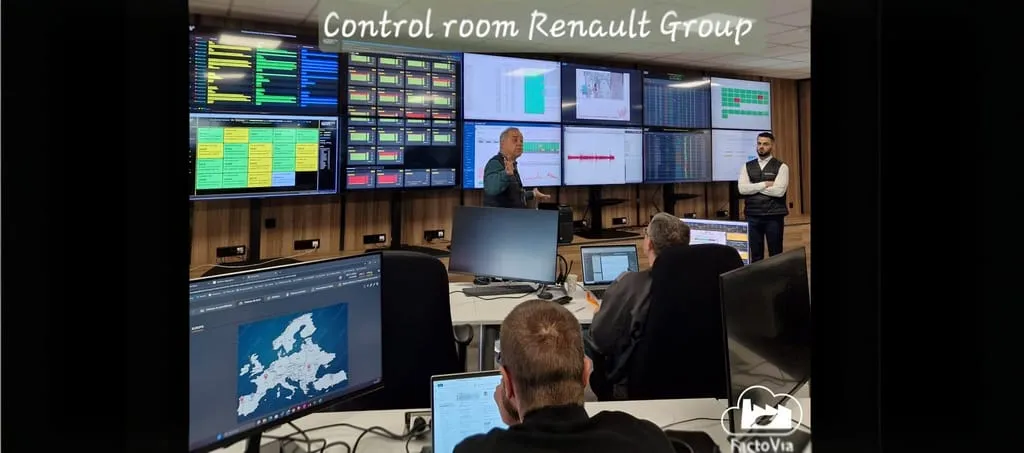
This is where the concept of a Unified Namespace becomes relevant. A Unified Namespace acts as a single semantic layer that maps every sensor, asset, and data stream to a consistent model. It does not care where the data lives. It just ensures that when you query "motor temperature on line 3," you get the same answer whether you ask from the edge, the cloud, or a dashboard in the control room.
I have seen companies try to build this kind of consistency with point-to-point integrations. It works for a while, but it breaks as soon as you add a new machine or change a PLC. A Unified Namespace approach, combined with a data mesh architecture, gives you flexibility without losing control.
Practical trade-offs in data ops
No approach is free. Stream processing gives you speed but adds complexity. A data catalog gives you clarity but requires discipline to maintain. Edge computing reduces latency but limits the compute power available for analytics. Every choice in data ops involves a trade-off between performance, cost, and maintainability.
For example, I worked with a site that wanted to run anomaly detection on every vibration signal from every motor. The stream processing pipeline they designed was elegant, but it required ten times the compute budget they had planned. They ended up sampling the signals at the edge and running full analysis only on the subset that exceeded a threshold. That is a good data ops decision: it balances fidelity with feasibility.
Another common trade-off involves data retention. A time-series database can store years of high-frequency data, but the cost grows with every sensor you add. Many teams now tier their storage, keeping high-resolution data for a few days on edge devices, then downsampling to minute-level averages for the cloud. The digital twin still gets the detail it needs, and the long-term archive stays affordable.
Connecting data ops to Industrie 4.0 and smart manufacturing
The Industrie 4.0 vision calls for a fully connected, self-optimizing factory. That vision depends on the Asset Administration Shell, a digital representation of every asset that lives alongside the physical machine. To keep an Asset Administration Shell current, you need continuous data ops. The shell cannot be a static document. It must update as the machine wears, as production schedules change, and as new data sources come online.
Smart manufacturing initiatives often fail not because the technology is immature, but because the data ops foundation is not in place. You can buy the best MQTT broker, the fastest Kafka cluster, and the most sophisticated digital twin platform. If you do not have the operational routines to manage metadata, handle schema changes, and monitor data quality, those tools will produce more noise than insight.
I have seen this pattern repeat across multiple industries. A team deploys a proof of concept for predictive maintenance. It works beautifully for three months on a single machine. Then they try to scale it to fifty machines, and the data pipeline collapses under the weight of schema drift, missing timestamps, and incompatible units. The solution is not a bigger database. It is better data ops from the start.
A realistic path forward
If your team is new to data ops, start small. Pick one production line or one asset type. Map the data flow from sensor to dashboard. Write down every transformation, every protocol conversion, and every manual step. That map is your current state. From there, identify the single biggest friction point. It might be that your MQTT broker drops messages under load, or that your data catalog is a shared spreadsheet no one trusts.
Fix that one thing. Then measure the impact. Did the digital twin update faster? Did the time to detect an anomaly shrink? Did the engineering team spend less time wrangling data? Those metrics are the proof that data ops matters.
Over time, you can expand the scope. Add stream processing for the most critical signals. Introduce a data mesh approach so that each domain team owns its data while still contributing to the global pipeline. Build governance rules that enforce data sovereignty without slowing down innovation. Each step builds on the last, and each step reduces the distance between the machine and the decision.
Data ops is not a product you buy. It is a practice you build. And for any industrial company serious about digital transformation, it is the foundation everything else rests on.